# streamx
**Repository Path**: myitgit/streamx
## Basic Information
- **Project Name**: streamx
- **Description**: StreamX 是一个 Apache Flink 极速开发框架
- **Primary Language**: Java
- **License**: Apache-2.0
- **Default Branch**: master
- **Homepage**: https://www.oschina.net/p/streamx
- **GVP Project**: No
## Statistics
- **Stars**: 0
- **Forks**: 24
- **Created**: 2021-05-24
- **Last Updated**: 2024-06-02
## Categories & Tags
**Categories**: Uncategorized
**Tags**: None
## README

🏳️🌈 StreamX 🏳️🌈
Make Flink|Spark easier!!!


**[Official Website](http://www.streamxhub.com)** |
**[Change Log](#)** |
**[Document](http://www.streamxhub.com/zh/doc/)**
English | [中文](README_CN.md)
# StreamX
Make Flink|Spark easier
> A magical framework that makes Flink development easier
## 🚀 Introduction
The original intention of `StreamX` is to make the development of `Flink` easier. `StreamX` focuses on the management of development phases and tasks. Our ultimate goal is to build a one-stop big data solution integrating stream processing, batch processing, data warehouse and data laker.


## 🎉 Features
* Scaffolding
* Out-of-the-box connectors
* Support maven compilation
* Configuration
* Support `Applicaion` and `Yarn-Per-Job` mode
* `start`, `stop`, `savepoint`, resume from `savepoint`
* Flame graph
* Notebook
* Project configuration and dependency version management
* Task backup and rollback
* Manage dependencies
* UDF
* Flink SQL WebIDE
* Catalog、Hive
* Full support from task `development` to `deployment`
* ...
## 🏳🌈 Components
`Streamx` consists of three parts,`streamx-core`,`streamx-pump` and `streamx-console`
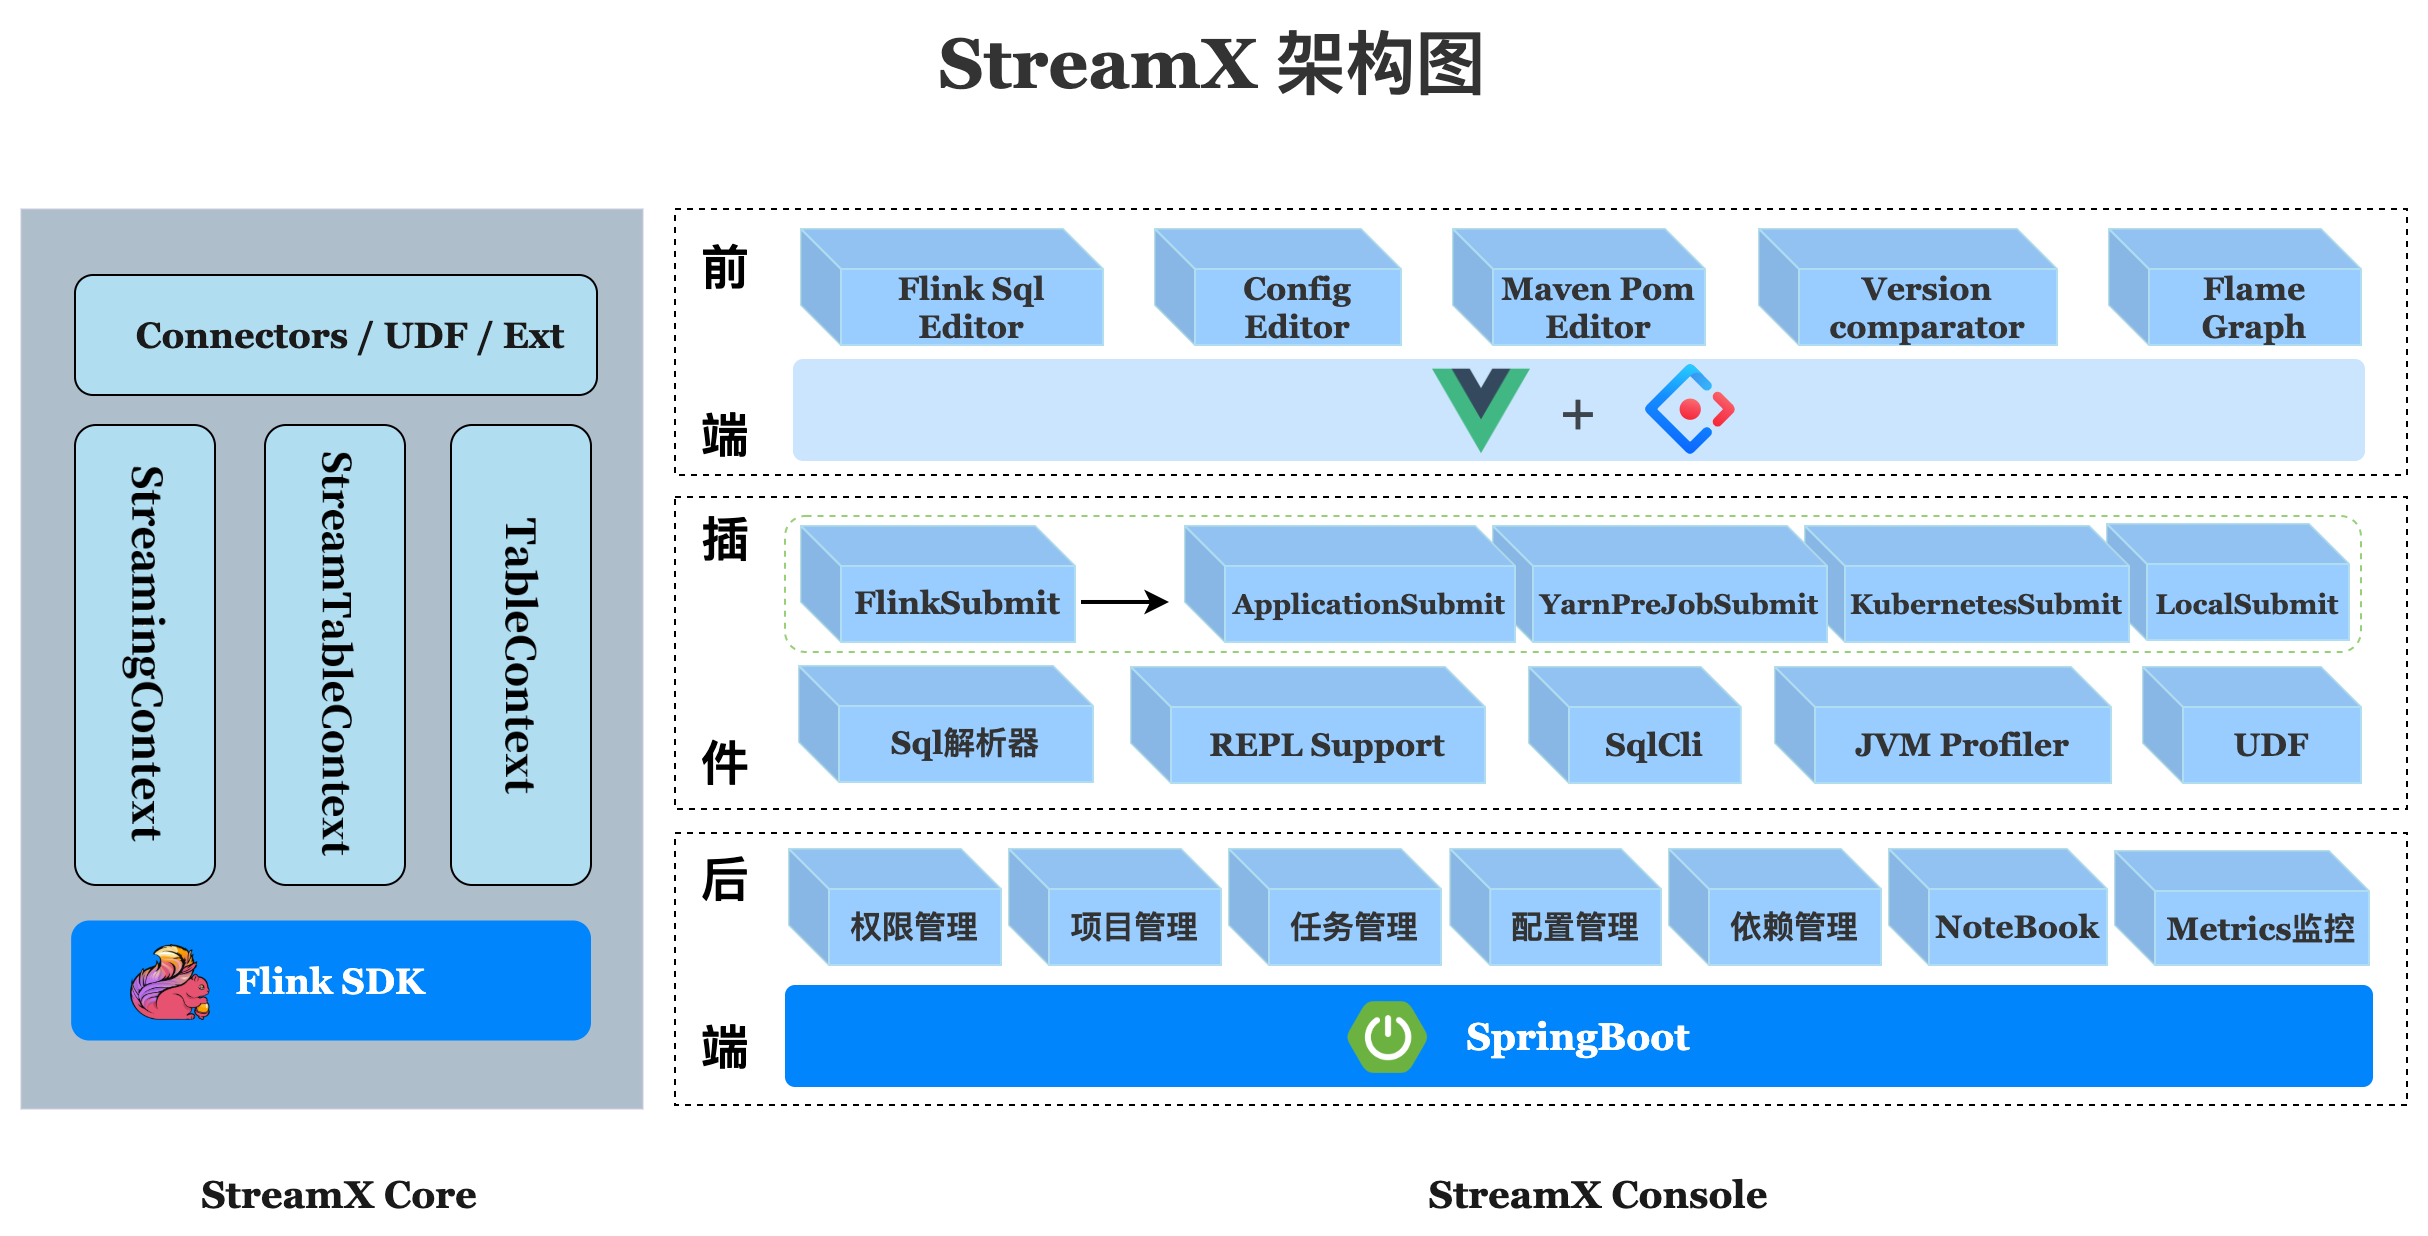
### 1️⃣ streamx-core
`streamx-core` is a framework that focuses on coding, standardizes configuration, and develops in a way that is better than configuration by convention. Also it provides a development-time `RunTime Content` and a series of `Connector` out of the box.
At the same time, it extends `DataStream` some methods, and integrates `DataStream` and `Flink sql` api to simplify tedious operations, focus on the business itself, and improve development efficiency and development experience.
### 2️⃣ streamx-pump
`streamx-pump` is a planned data extraction component, similar to `flinkx`. Based on the various `connector` provided in `streamx-core`, the purpose is to create a convenient, fast, out-of-the-box real-time data extraction and migration component for big data, and it will be integrated into the `streamx-console`.
### 3️⃣ streamx-console
`streamx-console` is a stream processing and `Low Code` platform, capable of managing `Flink` tasks, integrating project compilation, deploy, configuration, startup, `savepoint`, `flame graph`, `Flink SQL`, monitoring and many other features. Simplify the daily operation and maintenance of the `Flink` task.
Our ultimate goal is to build a one-stop big data solution integrating stream processing, batch processing, data warehouse and data laker.
* [Apache Flink](http://flink.apache.org)
* [Apache YARN](http://hadoop.apache.org)
* [Spring Boot](https://spring.io/projects/spring-boot/)
* [Mybatis](http://www.mybatis.org)
* [Mybatis-Plus](http://mp.baomidou.com)
* [Flame Graph](http://www.brendangregg.com/FlameGraphs)
* [JVM-Profiler](https://github.com/uber-common/jvm-profiler)
* [Vue](https://cn.vuejs.org/)
* [VuePress](https://vuepress.vuejs.org/)
* [Ant Design of Vue](https://antdv.com/)
* [ANTD PRO VUE](https://pro.antdv)
* [xterm.js](https://xtermjs.org/)
* [Monaco Editor](https://microsoft.github.io/monaco-editor/)
* ...
Thanks to the above excellent open source projects and many outstanding open source projects that are not mentioned, for giving the greatest respect, special thanks to [Apache Zeppelin](http://zeppelin.apache.org), [IntelliJ IDEA](https://www.jetbrains.com/idea/),
Thanks to the [fire-spark](https://github.com/GuoNingNing/fire-spark) project for the early inspiration and help.
## 👻 Why not...❓
### Apache Zeppelin
[Apache Zeppelin](https://zeppelin.apache.org) is a Web-based notebook that enables data-driven, interactive data analytics and collaborative documents with SQL, Java, Scala and more.
At the same time we also need a one-stop tool that can cover `development`, `test`, `package`, `deploy`, and `start`.
`streamx-console` solves these pain points very well, positioning is a one-stop stream processing platform, and has developed more exciting features (such as `Flink SQL WebIDE`, `dependency isolation`, `task rollback `, `flame diagram` etc.)
### FlinkX
[FlinkX](http://github.com/DTStack/flinkx) is a distributed offline and real-time data synchronization framework based on flink widely used in DTStack, which realizes efficient data migration between multiple heterogeneous data sources.
`StreamX` focuses on the management of development phases and tasks. The `streamx-pump` module is also under planning, dedicated to solving data source migration, and will eventually be integrated into the `streamx-console`.
## 🍼 Feedback
You can quickly submit an issue. Before submitting, please check the problem and try to use the following contact information! Maybe your question has already been asked by others, or it has already been answered. Thank you!
You can contact us or ask questions via:
- [New an issue](https://github.com/streamxhub/streamx/issues/new)
- [Join us](#-Join-us)
## 💰 Donation
Are you **enjoying this project** ? 👋
If you like this framework, and appreciate the work done for it to exist, you can still support the developers by donating ☀️ 👊
| WeChat Pay | Alipay |
|:----------|:----------|
|  |
 |
### 🏅 Backers
Thank you to all our backers!
## 💬 Join us
[StreamX]((http://www.streamxhub.com/#/)) enters the high-speed development stage, we need your contribution.

 join us